Scaling in System Design: Vertical vs. Horizontal Explained

Scaling in System Design: Scaling refers to a system’s ability to handle increased load (more requests, more users, more data) by adjusting its resources. The goal is to ensure that the system continues to perform well as demand grows.
Why Scaling Matters
Almost every successful product eventually outgrows the machine it started on. A Spring Boot API that comfortably serves a few hundred users from a single server can slow to a crawl when a marketing campaign, a festive sale or a viral post sends ten times the usual traffic its way. Scaling is how you make sure that growth shows up as more happy users rather than timeouts, failed payments and angry support tickets.
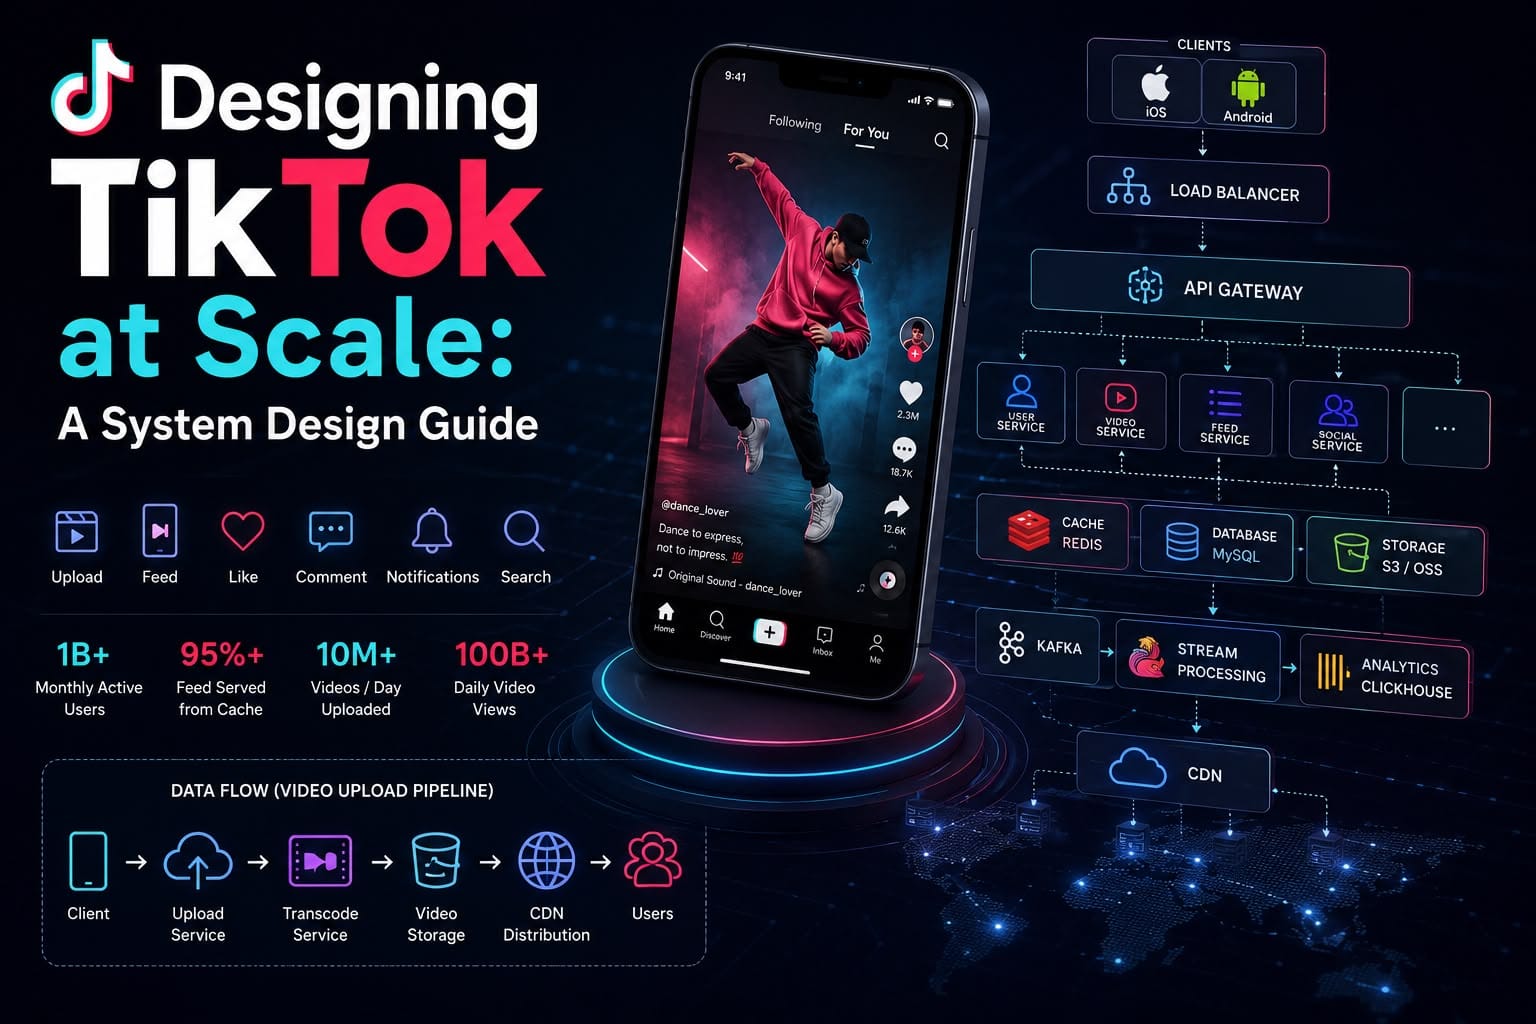
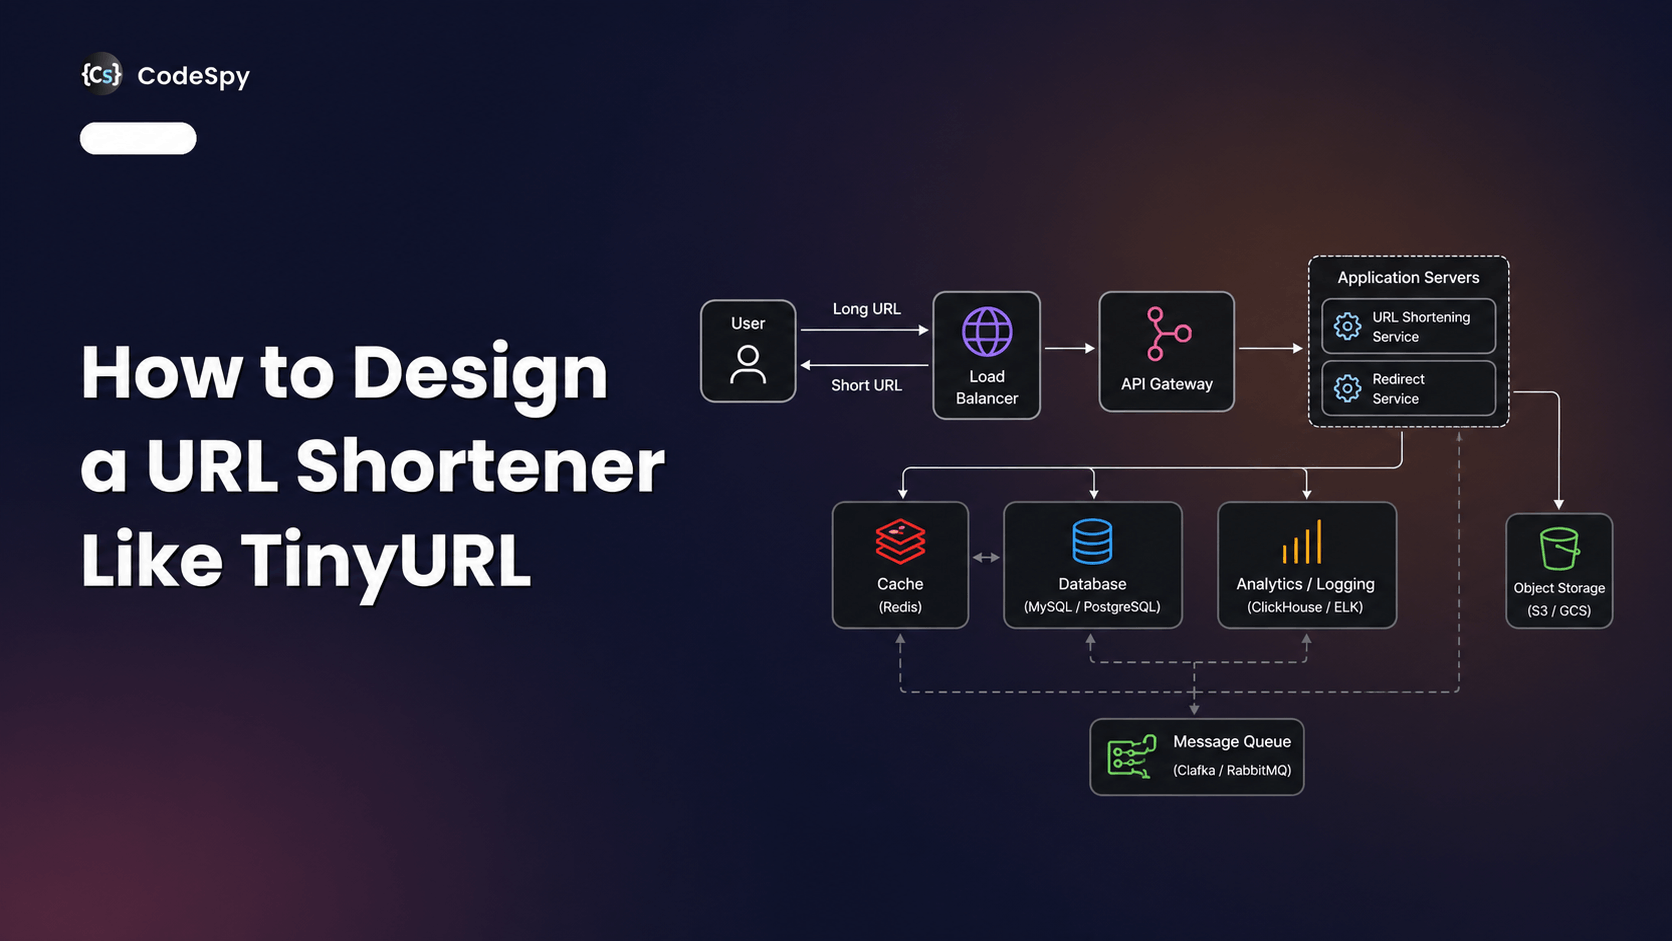
It is also one of the first topics an interviewer probes in any system design round. Whether you are designing a URL shortener, a video platform like TikTok or a payment system, you will be asked how the design holds up at 10x and 100x the load. Understanding the two fundamental approaches, and their trade-offs, is the foundation for every one of those answers.
Signs your system needs to scale
- Rising latency under load – p95 and p99 response times climb during peak hours even though the code has not changed.
- Resource saturation – CPU sits above 70–80%, memory is close to the limit, or the database runs out of connections.
- Growing error rates – more HTTP 5xx responses, request timeouts or queue backlogs that take minutes to drain.
- Upcoming traffic events – a product launch, a sale or a big partner integration that you already know will multiply traffic.
- Data growth – tables with hundreds of millions of rows where queries that used to take milliseconds now take seconds.
Once you see these signals, you have two basic options: make the machine bigger, or add more machines.
There are two main types:
- Vertical Scaling (Scaling Up)
- Horizontal Scaling (Scaling Out)
1. Vertical Scaling (Scaling Up)

Vertical scaling means increasing the capacity of a single machine. This can be achieved by adding more CPU, RAM, disk, or network bandwidth.
Example: Upgrading a server from 4 cores, 16GB RAM to 16 cores, 64GB RAM.
Pros:
- Simple to implement (just upgrade the hardware).
- No code or architecture changes required.
- Useful for monolithic and small-scale applications.
- Easier to manage since only one system needs to be maintained.
Cons:
- Limited by hardware (you can’t scale forever).
- High-end machines become expensive quickly.
- Single point of failure remains → downtime risk increases.
2. Horizontal Scaling (Scaling Out)

Horizontal scaling means adding more machines/servers to share the load. Work is distributed across multiple load balancers, clusters, or distributed systems.
Example: Instead of one large server, run 10 smaller servers behind a load balancer.
Pros:
- Almost unlimited scalability.
- Better performance (load is distributed).
- High availability and fault tolerance (failure in one node can be handled by others).
Cons:
- More complex to manage.
- Requires synchronization and consistency across nodes.
- Needs orchestration tools (e.g., Kubernetes).
3. Key Differences: Vertical vs Horizontal Scaling in System Design
| Aspect | Vertical Scaling (Scaling Up) | Horizontal Scaling (Scaling Out) |
|---|---|---|
| Approach | Add more power (CPU, RAM) to a single machine | Add more machines to distribute the workload |
| Example | Upgrading server CPU, RAM, or storage | Adding multiple servers behind a load balancer |
| Complexity | Relatively simple to implement | More complex due to distributed system architecture |
| Scalability | Limited by maximum capacity of a single machine | Virtually unlimited by adding more nodes |
| Fault Tolerance | Low — failure of the machine can cause downtime | High — failure of one node doesn’t take down the system |
| Cost | Becomes expensive as hardware limits are reached | More cost-efficient over time with commodity hardware |
4. When to Use Vertical Scaling
- Best for systems that cannot be easily distributed.
- Quick fix when apps need more resources.
- Examples:
- Databases like PostgreSQL/MySQL.
- Monolithic applications (e.g., Java Spring Boot app running on a single server).
5. When to Use Horizontal Scaling
- Best for systems handling massive growth (millions of users).
- High availability and fault tolerance are priorities.
- Examples:
- Social media platforms (Facebook, Twitter, YouTube).
- Search engines (Google distributes queries across servers).
- Content Delivery Networks (CDNs) serving content closer to users.
6. Hybrid Scaling (Combining Both)

Often, real-world systems use a combination of both vertical and horizontal scaling.
- First, give each machine a decent baseline (vertical scaling).
- Example: Upgrade from 1-core, 2GB server → 16-core, 64GB server.
- Then, add multiple such machines (horizontal scaling) to handle extra load.
Benefits:
- Efficiency and cost optimization.
- Balanced performance.
- Fault tolerance + power.
Real-World Examples:
- Netflix → Each VM has vertical capacity, but thousands run across regions.
- Kubernetes clusters → Each pod runs on a vertically scaled node, and pods scale horizontally with traffic.
Prerequisite for Scaling Out: Stateless Services
Horizontal scaling only works smoothly when any server can handle any request. That means your application servers should be stateless: they should not keep user sessions, uploaded files or in-progress work in local memory or on local disk.
- Sessions – store them in a shared store such as Redis (Spring Session makes this a configuration change), or use stateless JWT tokens.
- Files and media – upload them to object storage such as Amazon S3 or Google Cloud Storage instead of the server’s file system.
- Background work – push long-running jobs onto a queue (Kafka, RabbitMQ, SQS) so any worker can pick them up.
- Configuration – keep it in environment variables or a config server, never hard-coded per machine.
If a load balancer can send a user’s next request to a different server and nothing breaks, your service is ready to scale out. If it relies on “sticky sessions” to keep working, that is a warning sign: losing one server will log users out or lose their work.
Scaling the Database Layer
Application servers are usually the easy part. The database is where most real-world scaling problems end up, because it holds state and every service depends on it. These are the standard techniques, roughly in the order teams adopt them:
1. Vertical scaling and query tuning
Before anything else, add indexes for slow queries, fix N+1 query patterns, and give the database server more CPU, RAM and faster disks. This is cheap, low-risk and often buys months or years of headroom.
2. Caching
Put a cache such as Redis or Memcached in front of the database for data that is read far more often than it is written: product catalogues, user profiles, configuration, feed results. A cache hit rate of 90% means the database only sees one in ten of those reads. The trade-off is staleness, so you need a clear invalidation strategy (time-based expiry, write-through, or explicit eviction on update).
3. Read replicas
Most applications read far more than they write. Read replicas copy data from the primary database and serve read-only queries, while all writes still go to the primary. This scales reads horizontally, with one catch: replication lag. A user who updates their profile and immediately reloads the page might briefly see the old value, so read-your-own-writes paths should go to the primary.
4. Partitioning and sharding
When a single primary can no longer handle the write volume or the data size, you split the data across multiple databases. Each shard holds a subset of the data, chosen by a shard key such as user ID or region. Sharding gives near-linear write scalability but makes cross-shard queries, joins and transactions much harder, so it is usually the last step rather than the first.
| Technique | Scales | Main trade-off |
|---|---|---|
| Vertical scaling + indexes | Reads and writes, up to hardware limits | Hard ceiling, single point of failure |
| Caching | Reads | Stale data, invalidation complexity |
| Read replicas | Reads | Replication lag |
| Sharding | Reads, writes and storage | Cross-shard queries, rebalancing, operational complexity |
Auto-Scaling in the Cloud
In cloud environments you rarely add servers by hand. Auto-scaling watches a metric and adds or removes instances automatically: AWS Auto Scaling Groups, Google Cloud managed instance groups, or the Kubernetes Horizontal Pod Autoscaler (HPA) for containers.
- Pick the right metric – CPU utilisation is the default, but request rate, queue depth or latency often reflect real load better.
- Set sensible limits – a minimum number of instances for baseline availability and a maximum to cap cost if something goes wrong.
- Account for warm-up time – a JVM service can take 30–60 seconds to start and warm up, so scale out early rather than at 95% CPU.
- Use scheduled scaling for known peaks – if traffic always spikes at 9 AM or during a sale, scale up ahead of time instead of reacting.
Common Scaling Mistakes
- Scaling before measuring – adding servers without load testing or profiling often moves the bottleneck instead of removing it.
- Scaling the app tier but not the database – ten new API servers just send ten times the connections to the same overloaded database.
- Keeping state on servers – in-memory sessions and local file uploads break as soon as traffic is spread across machines.
- Ignoring connection limits – each new instance opens its own pool of database connections; use a pooler (for example PgBouncer or RDS Proxy) when instance counts grow.
- Premature sharding – sharding a database that a bigger instance, an index and a cache could handle adds complexity you then live with forever.
How to Discuss Scaling in a System Design Interview
Interviewers are less interested in whether you know the words “vertical” and “horizontal” than in whether you can reason about where a specific system will break. A strong answer usually follows this shape:
- Estimate the load – requests per second at average and peak, read/write ratio, and data growth per day.
- Start simple – a single, vertically scaled server and database is a perfectly valid starting point for modest numbers.
- Find the first bottleneck – usually the database or a single hot service, and explain how you would detect it with metrics.
- Scale the stateless tier horizontally – add a load balancer and multiple app instances, and point out that this requires stateless services.
- Scale the data tier deliberately – caching first, then read replicas, and sharding only when writes or data size demand it.
- Discuss trade-offs – cost, consistency, operational complexity and how the design affects availability and reliability.
Walking through a design in this order shows the interviewer that you scale for real reasons, not by default.
Frequently Asked Questions
Is horizontal scaling always better than vertical scaling?
No. Vertical scaling is simpler, cheaper to operate and perfectly adequate for many applications, especially early on. Horizontal scaling becomes necessary when you hit hardware limits, need fault tolerance across machines, or have unpredictable traffic. Most production systems use both.
Can a relational database like MySQL or PostgreSQL scale horizontally?
Yes, but with more effort than a stateless service. Read replicas scale reads with little application change. Scaling writes requires sharding, either in the application or with tools such as Vitess for MySQL or Citus for PostgreSQL.
What is the difference between scalability and performance?
Performance is how fast the system handles a single request or a fixed load. Scalability is how well it keeps that performance as load grows. A system can be fast for ten users and fall over at ten thousand; that is a scalability problem, not a performance one.
Does using Kubernetes mean my application is scalable?
Not by itself. Kubernetes makes it easy to run and auto-scale many copies of a service, but the service still has to be stateless, and the database and other shared dependencies still have to scale. Kubernetes is the mechanism, not the design.
Conclusion
- Vertical scaling is simple but limited and costly.
- Horizontal scaling provides massive scalability but requires complexity.
- Hybrid scaling combines both for optimal results in large-scale systems.
There is no single “right” way to scale. Start with the simplest design that meets today’s load, measure where it strains, and scale the specific bottleneck: bigger machines first, more machines when you need fault tolerance or headroom beyond one box, and a carefully scaled data tier underneath both. That habit of measuring, then scaling deliberately, is exactly what interviewers and production systems reward.
1 comment